Guides to understand AI
From concept to hardware: everything you need to run AI yourself, locally or in the cloud, without breaking the bank.
 ~ 12 min
Local AI vs cloud AI: which should you choose?
Privacy, cost, performance: we compare local inference vs cloud API to help you decide.
Read guide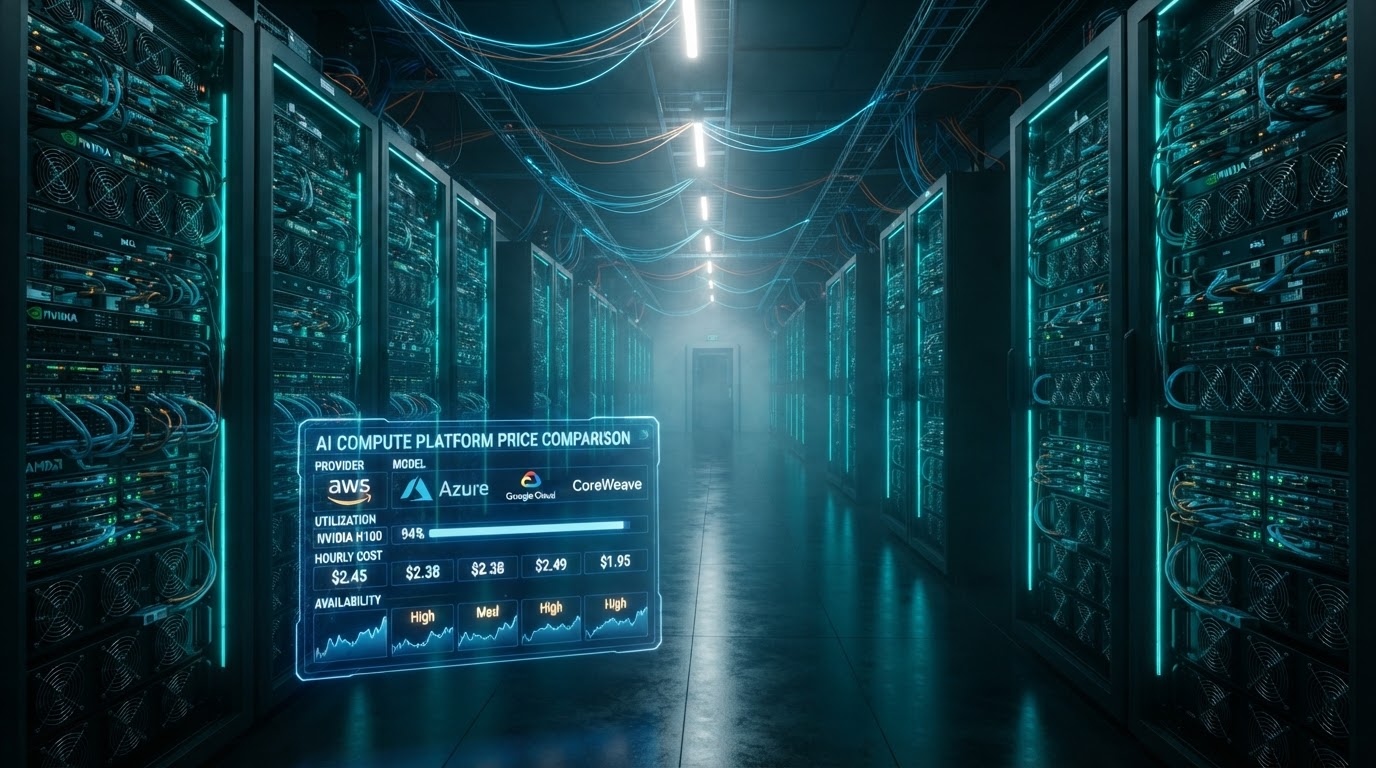 ~ 14 min
VPS, Vast.ai, RunPod: where to run your models?
From a classic VPS to hourly spot GPUs: the guide to AI infrastructure without buying hardware.
Read guide ~ 13 min
LLMs, models and harnesses: the AI vocabulary
The difference between an LLM, a foundation model, a fine-tune, quantization, and what an evaluation “harness” actually is.
Read guide ~ 16 min
The hardware to run AI yourself
GPU, RAM, NVMe vs SATA SSD: how to size a machine for inference and fine-tuning.
Read guide ~ 11 min
High-end workstations for AI
Threadripper, Mac Studio, multi-GPU: pro configurations to push local AI to its maximum.
Read guide ~ 13 min
Mac mini and local AI: the real guide (2026)
Hyped or outdated? We separate myth from reality on the Mac mini as an AI inference station.
Read guide ~ 14 min
DGX Spark vs AMD Mini PC vs Mac mini: the showdown
NVIDIA DGX Spark, Strix Halo, Mac mini M4: three opposing philosophies for local AI in 2026. VRAM, bandwidth, price, use cases.
Read guide ~ 12 min
Hermes 2.3: what's new in Nous Research's model
Reliable function calling, stronger steerability, agentic loops: what Hermes 2.3 really brings and how to use it locally or via API.
Read guide ~ 13 min
Evaluation harnesses: what they are and why they're crucial
lm-eval, lighteval, OpenCompass: without an evaluation harness you're picking a model at random. The guide to succeeding at an AI project.
Read guide ~ 15 min
AI assistants compared: Grok, ChatGPT, Claude, Gemini, Muse…
Grok, ChatGPT, Claude, Gemini, Muse, Le Chat, DeepSeek, Perplexity: strengths, weaknesses, pricing and use cases of every major AI assistant in 2026.
Read guide